在开源AI绘画模型领域,Flux模型是众多衍生开发的基础。然而,在二次元领域,尤其是日式风格方面,情况有所不同。目前,大量用户依然以SDXL模型为基础进行衍生开发。在开源社区中,Pony、Illustrious XL等微调SDXL模型被广泛使用,并在此基础上展开二次开发。近期,Illustrious XL推出了2.0版本,让我们来了解一下这一版本的亮点与突破。
Illustrious XL 1.0-2.0的迭代目标
Illustrious XL 1.0-2.0系列的核心目标是实现1536分辨率的稳定原生生成,并显著提升自然语言理解能力。尽管在早期版本中,用户有时能够观察到1024×1536分辨率的成功生成,但这些生成结果并不稳定。同样,512×512的生成偶尔会出现不需要的伪影。这些不稳定性背后的原因是什么?
- 官方介绍:https://www.illustrious-xl.ai/blog/7
- 模型地址:https://www.seaart.ai/zhCN/models/detail/cvbp2qle878c7387sppg (目前尚未开放下载)
早期版本不稳定的原因
早期版本的不稳定性主要源于模型在这些分辨率上未能有效泛化或训练。使用小数据集填补这些差距的训练往往会导致某些分辨率上的过拟合。这意味着模型会将特定分辨率与特定概念关联起来,从而在多样化生成中变得不可靠。一个形象的类比是“广角镜头”效应:如果数据集中常见广角镜头,模型在给定广角分辨率时自然会生成较小的人物,因为这是它学会泛化的方式。
为了解决这一问题,Illustrious XL v2.0进行了大量数据集的训练,规模相当于原始v0.1的训练,以消除跨分辨率和数据集的偏见。
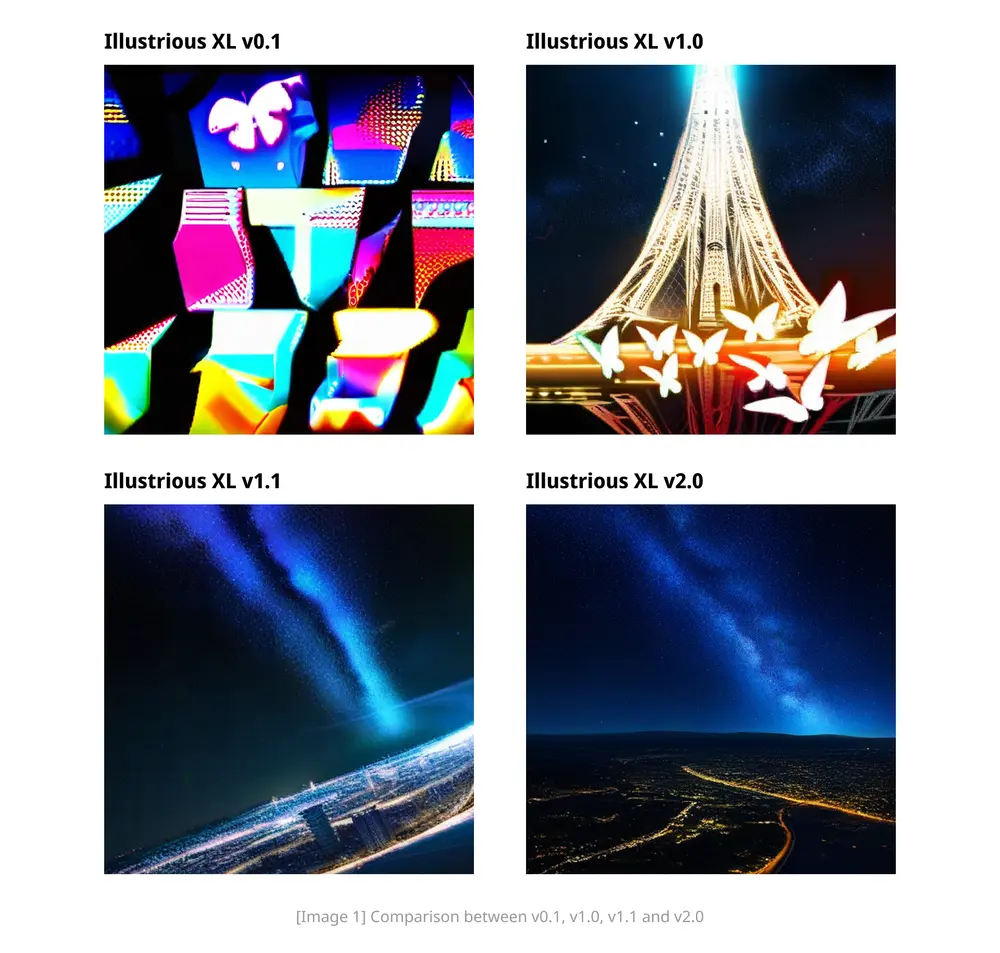
提示词: “stylish, no humans, city light, black theme, dim lighting, high contrast, night sky, masterpiece, absurdres, depth of field, butterflies, extremely aesthetic, absurdres, wallpaper, panorama, city background, neon, milky way, photo background, 512×512 generation”
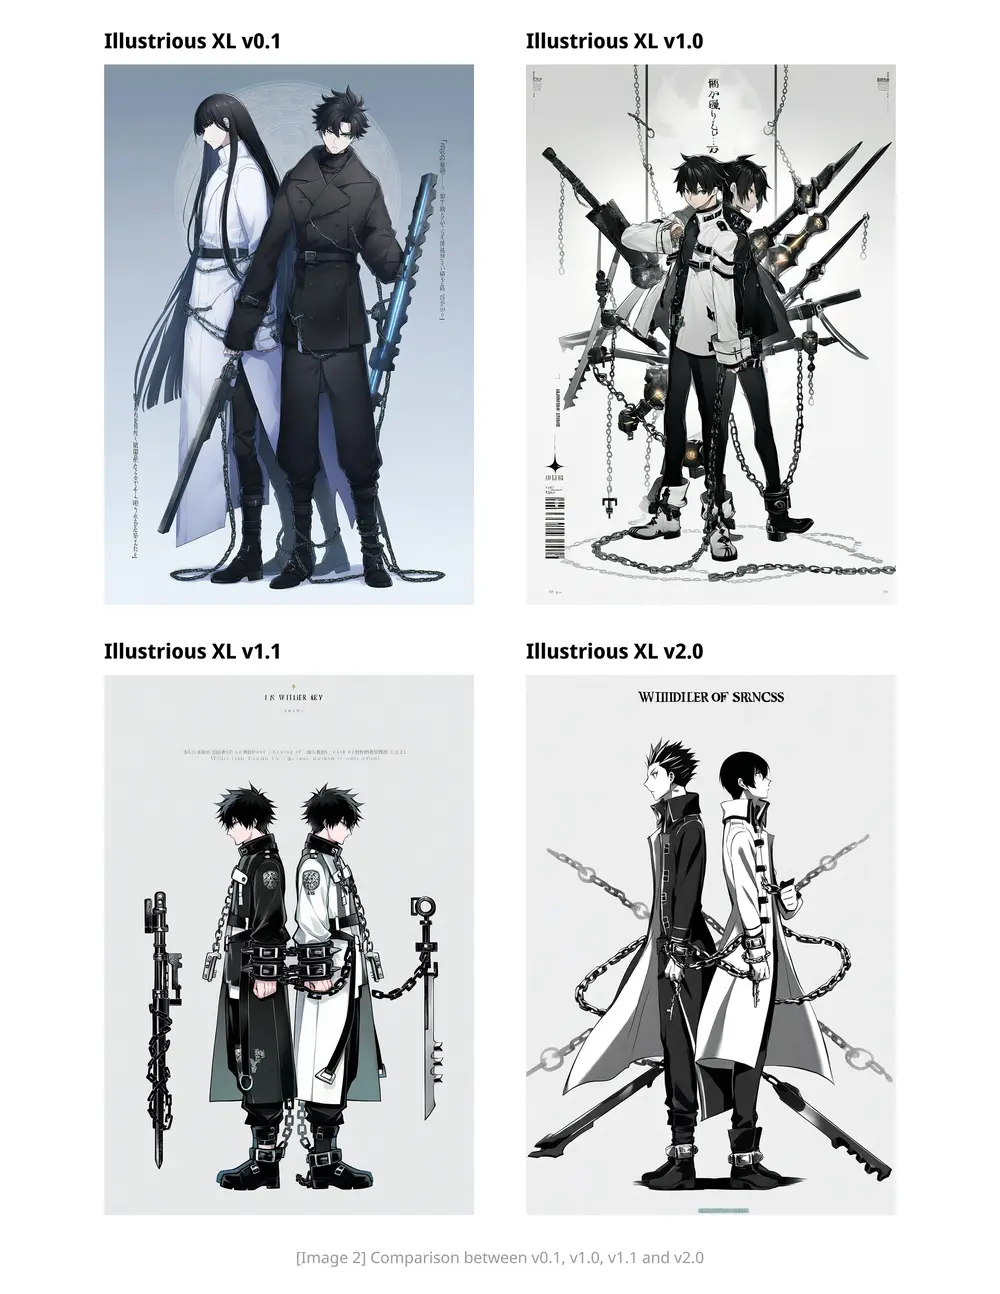
提示词: “The image features two characters,each with distinct black and white outfits,standing back-to-back. The character on the left wears a white coat with black accents,black pants,and boots,and is chained at the wrists and ankles. The character on the right is dressed in a black coat with white accents,black pants,and boots,also chained at the wrists and ankles. Both characters have spiked black hair and wield large key-shaped weapons. The background is white,and the text \”Wielder Of The Key\” and \”Controls Light & Darkness\” is displayed above and below the characters,respectively”
反向提示词: “worst quality, low quality, lowres, low details, bad quality, poorly drawn, bad anatomy, multiple views, bad hands, blurry, artist sign” Steps: 28, Sampler: Euler a, Schedule type: Automatic, CFG scale: 7.5, Seed: 3420215296, Size: 1248×1824
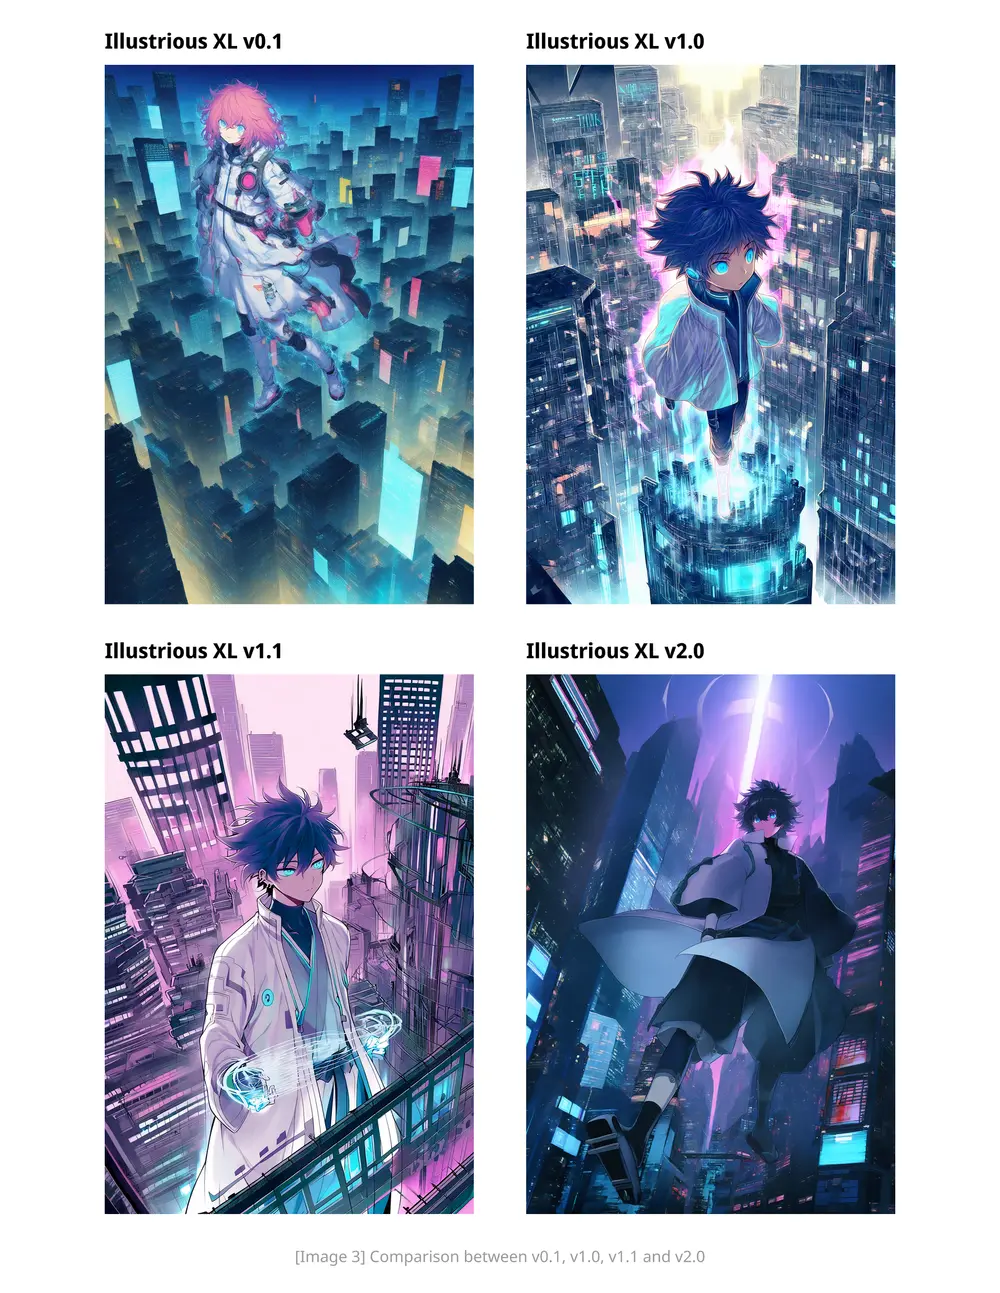
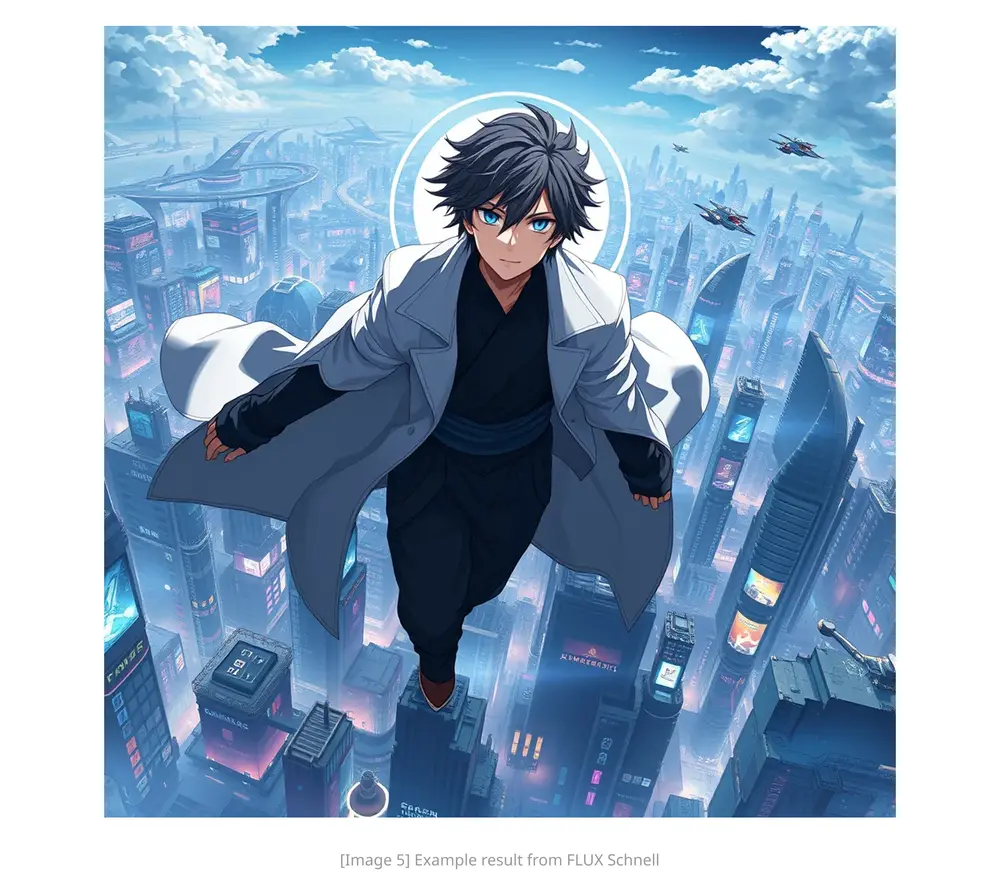
提示词: “Generate a highly detailed anime-style illustration of a young man floating serenely above a sprawling, futuristic cityscape. The boy has dark, messy hair and piercing blue eyes. He’s wearing a long, flowing white coat over dark, streamlined clothing – think a mix of traditional Japanese garments and futuristic techwear. His expression is calm and confident, almost detached. He is surrounded by a faint, glowing aura of light, possibly blue or white. Below him is a vast sci-fi city, filled with towering skyscrapers, holographic advertisements, and flying vehicles. The city should have a vibrant color palette – neon blues, purples, and pinks contrasting with darker metallic structures. There should be a sense of depth and scale, with buildings receding into the distance. The overall atmosphere should be epic and awe-inspiring, suggesting a powerful and mysterious character overlooking a technologically advanced world. Focus on dynamic lighting and detailed textures to create a visually stunning image. wlop, quasarcake, masterpiece”
与其他模型的基准测试
我们的目标很明确:在高分辨率下实现对自然语言的稳健性,并希望Illustrious v2及以上版本能达到一个新的高度。将Illustrious XL v2.0与NoobAI-XL和Animagine XL 4.0进行比较,可以明显看出其在提示遵循、风格保留和细节生成方面的关键改进。
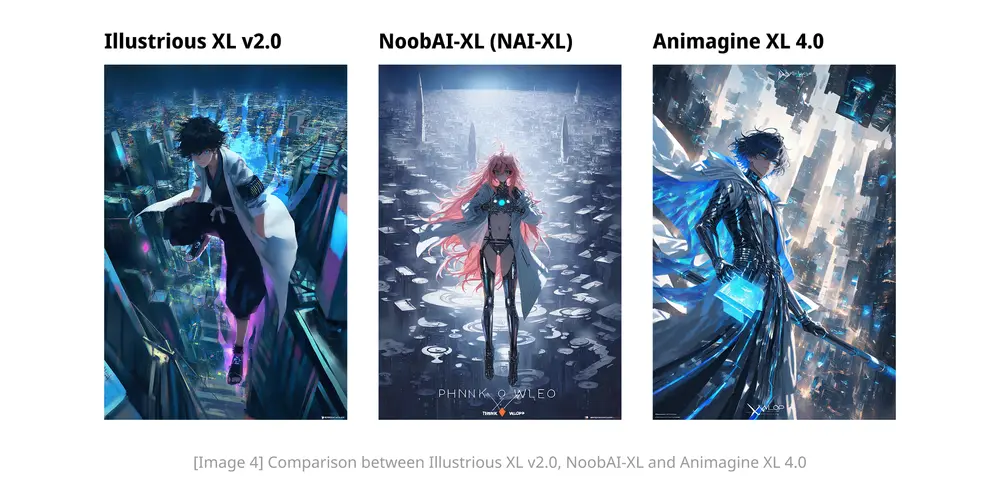
然而,仅仅遵循提示是不够的。以FLUX Schnell为例,它在提示遵循方面表现良好,但缺乏插图质量和风格。我们追求的是更好的提示遵循(对齐)与插图相关功能的结合,这不仅仅是美感,也不仅仅是单纯的计算。
指令调整与基础模型性能
Illustrious XL仍然是一个“用于额外微调的基础模型”,类似于未经指令调整的大型语言模型。我们在实际应用中看到的几乎每个模型都是经过指令调整或“微调”的变体。这是因为,刚预训练的模型并不意味着它会生成良好或优选的结果。几乎所有模型都会经历美学调整阶段以优化偏好,但美学调整可能会显著降低模型的“额外训练能力”。许多经过微调的美学模型在视觉上表现良好,但在训练时可能存在一些问题。
美学模型或错误训练的模型在训练中是灾难性的——这也是Illustrious XL构建的根本原因。我们希望模型从训练开始就具备良好的基础。然而,美学模型在视觉上确实更具吸引力——即使只是简单地与LoRA或其他模型合并。
美学调整与性能影响
我们推出了Illustrious XL v2.0的美学调整变体——v2.0 Aesthetic。该模型在泛化与美学精炼之间取得了平衡,同时保持了与v0.1~v2.0训练的LoRAs的兼容性。美学调整增强了模型生成视觉上吸引人的图像的能力,如自动模型评估所示。核密度估计(KDE)图突显了v2.0 Aesthetic在超过6000张图像样本中的“得分优化”重点。
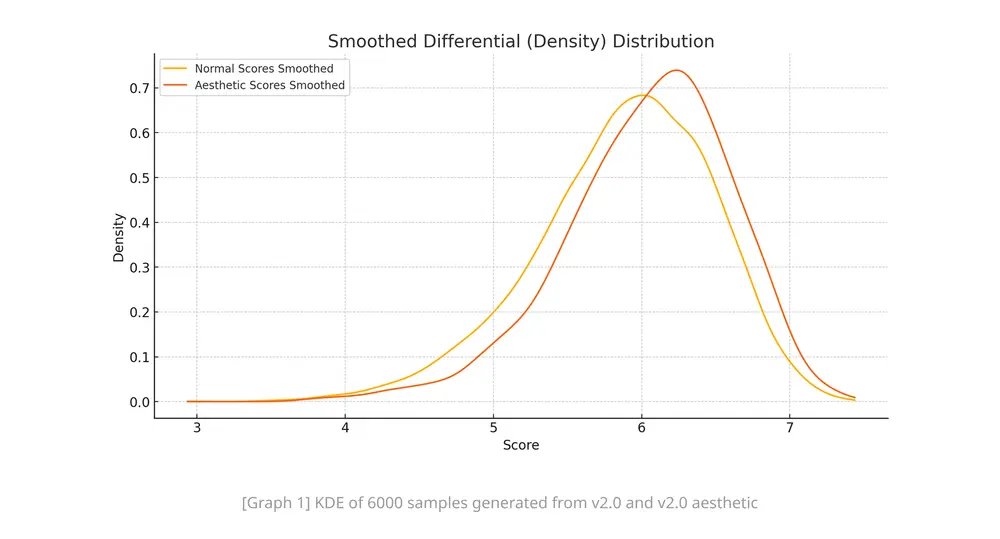
然而,由于美学调整,美学模型的训练可能并不顺利。我们强烈推荐使用v2-base作为训练的起始模型,而不是美学调整的变体。在此,我们再次强调,美学模型的训练难度较大,希望开发者们在实践中多加注意。
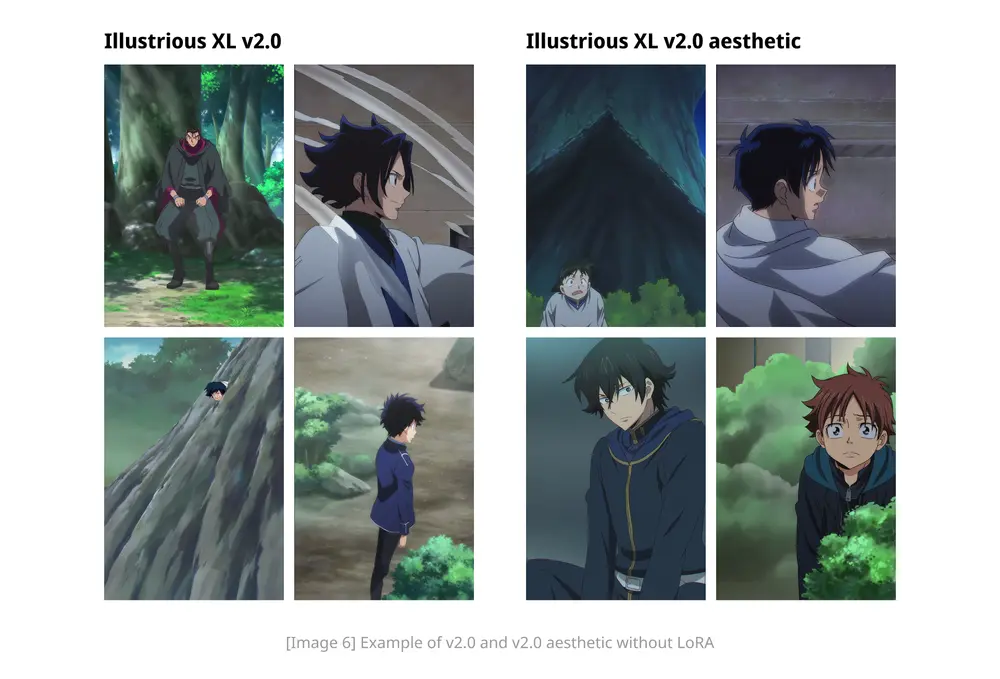
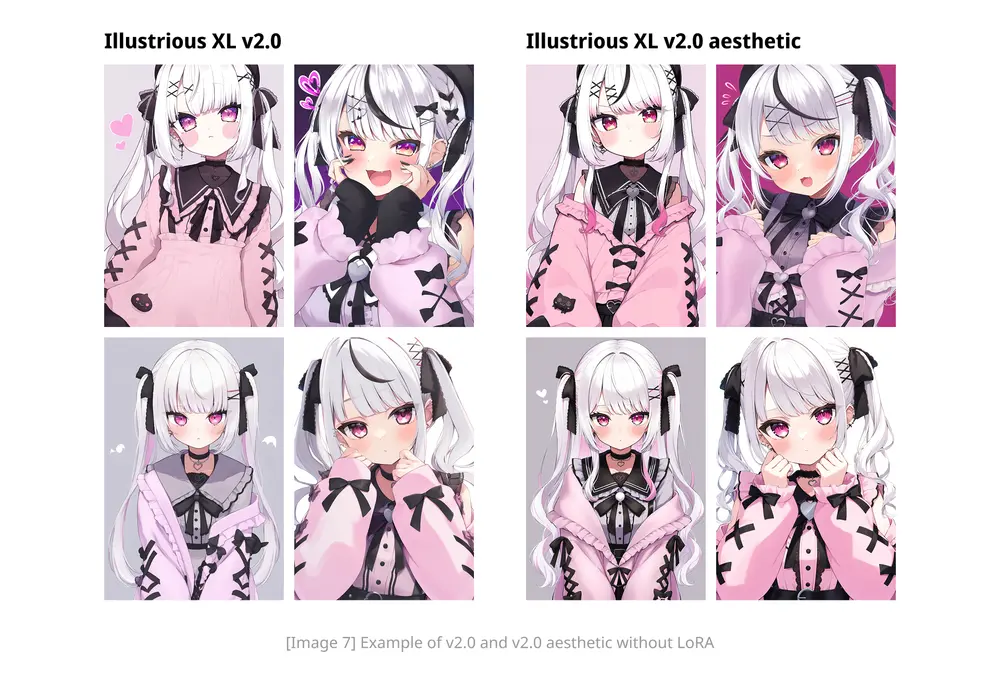
V2.0 Aesthetic生成的图像示例
最后,我们展示了与v2.0+模型兼容的LoRA生成示例。通过“可控”功能,我们可以实现一些很酷的效果,例如“2个女孩,站立,肩并肩,疯狂的mita(miside),yuitsuka inori,lora:new_chars:1,微笑,杰作,像素艺术,杰作”。
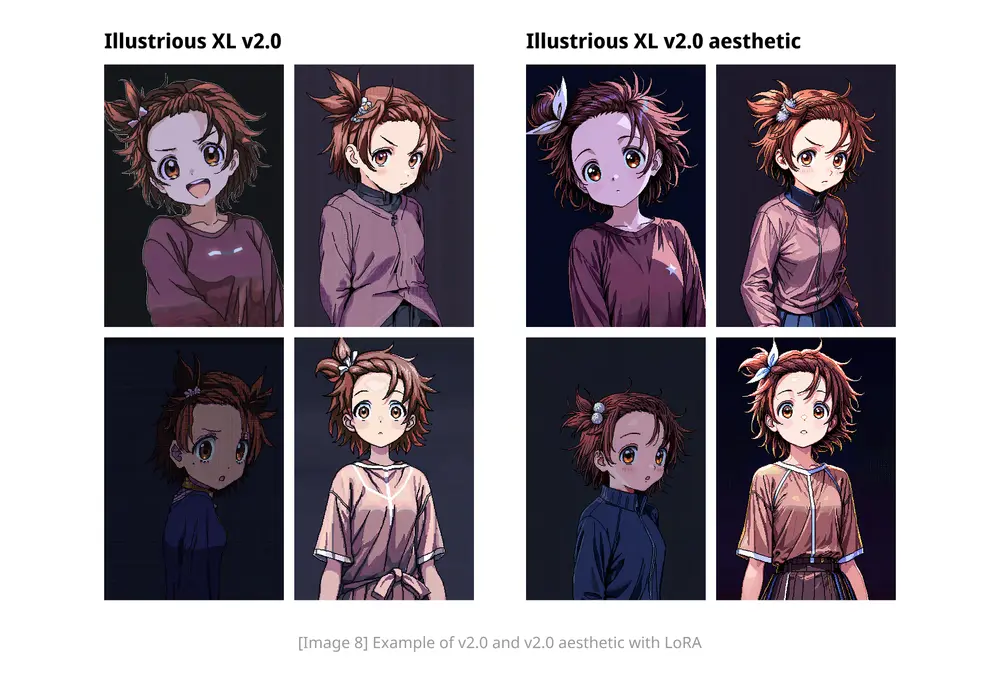
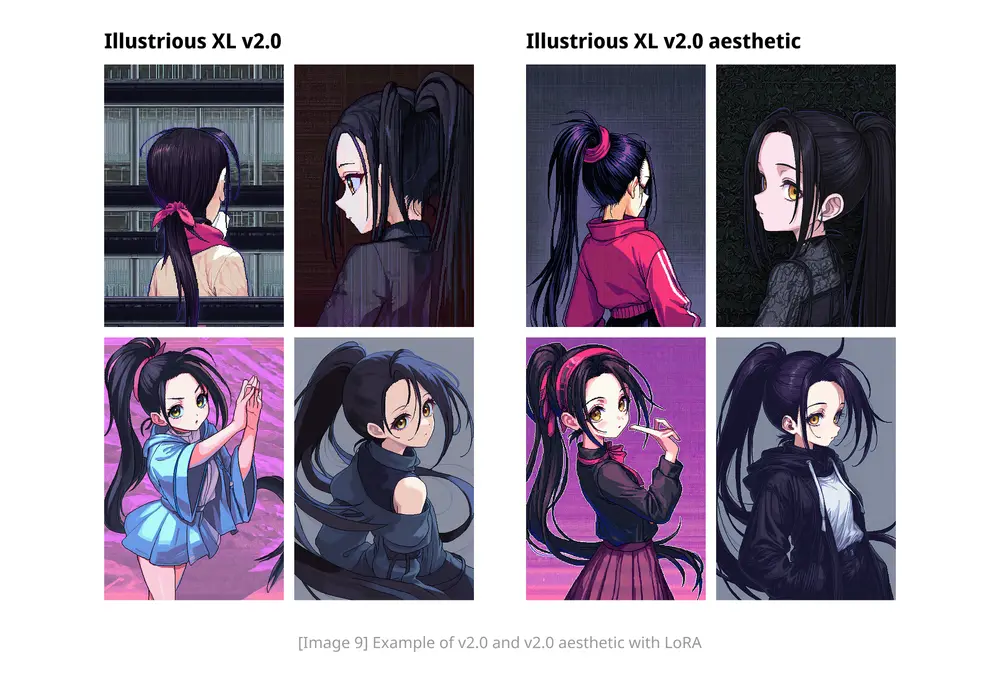
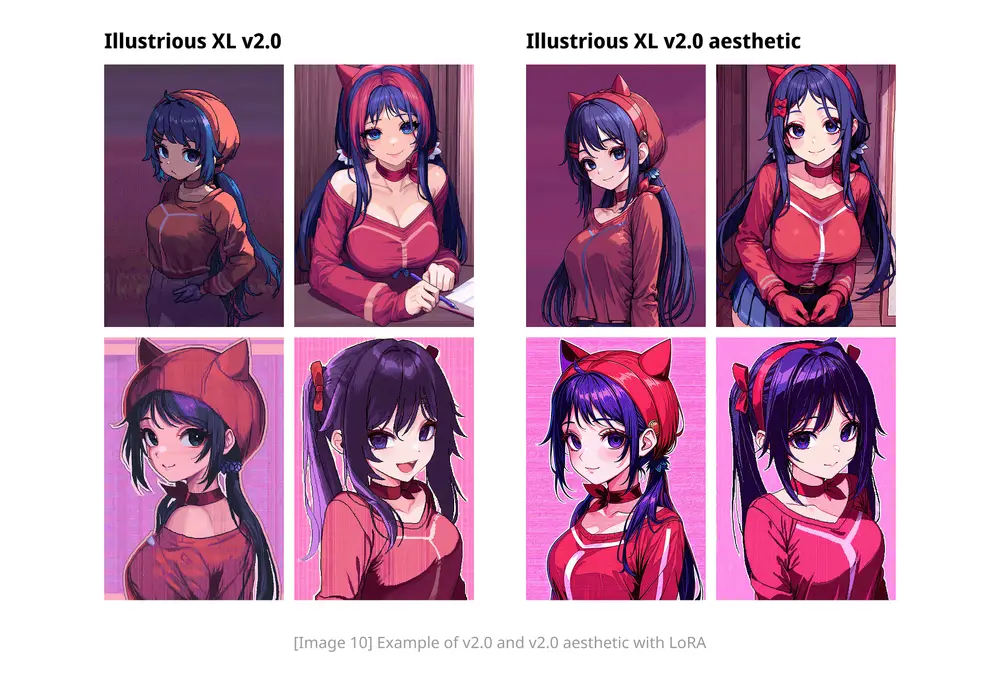
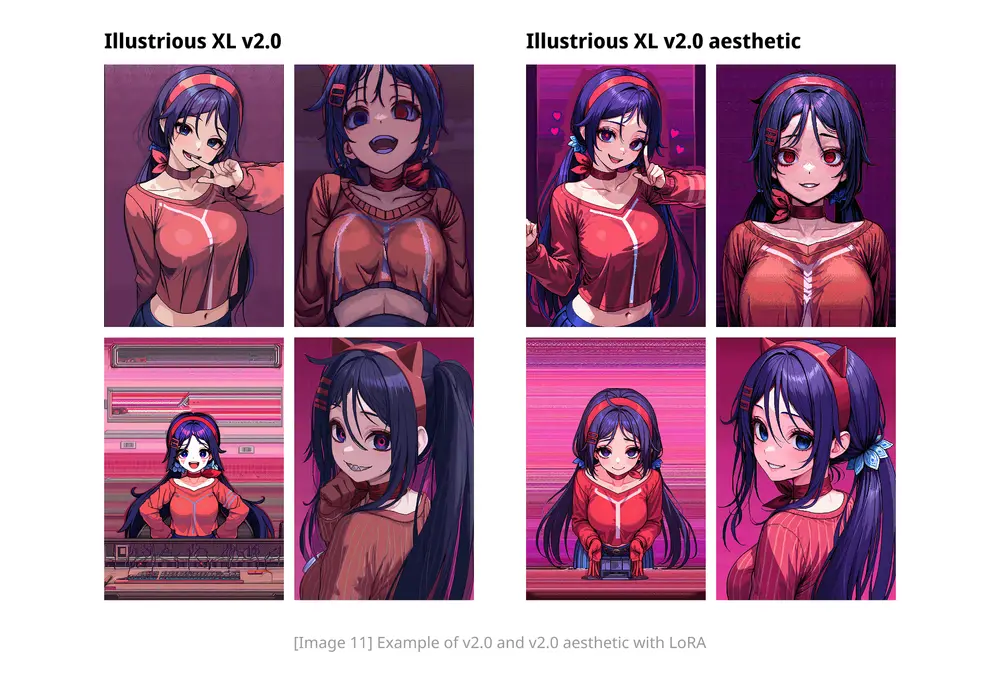
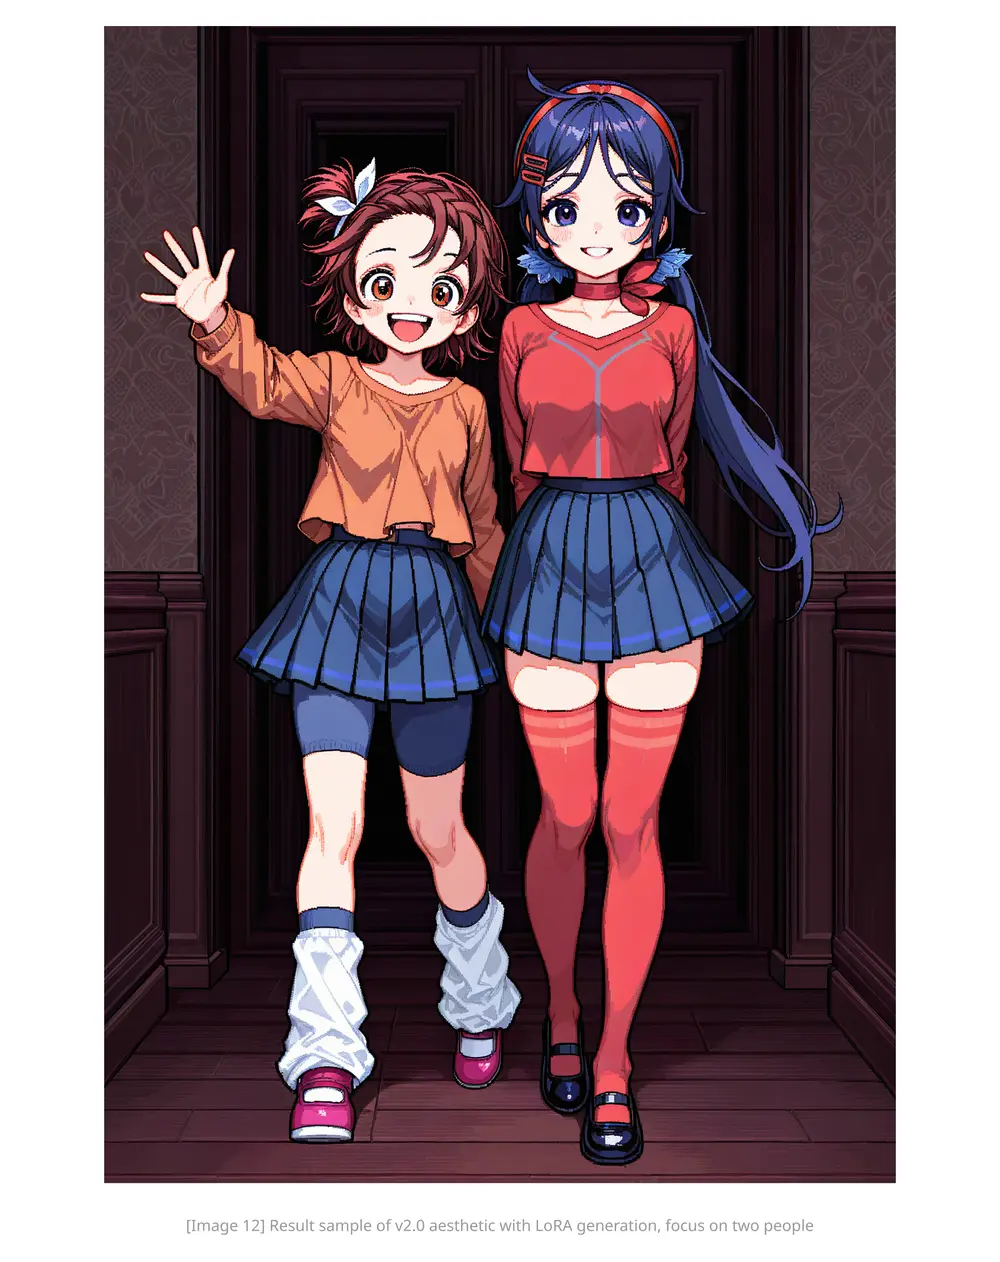
关于LoRA训练方法的学术细节,开发者将在近期正式披露,敬请期待!
© 版权声明
文章版权归作者所有,未经允许请勿转载。